HOWTO · PostgreSQL
How to Find and Delete Duplicate Records in a Database in PostgreSQL
This article shows how to find duplicate records in a database and then delete them in PostgreSQL.
On this page
To find duplicates in PostgreSQL, group by the columns that define a duplicate and keep groups whose count is greater than one. To remove extras safely, use ROW_NUMBER() within those same groups, preview rows numbered after the survivor, and delete by a stable unique key such as sid. The right comparison columns depend on your data rule: matching names are not necessarily duplicate student records.
PostgreSQL Duplicate-Detection Example Schema
This article uses a Student table with a primary key and three descriptive columns. The SQL examples are query illustrations; the configured runtime does not execute PostgreSQL statements, so no database output is claimed.
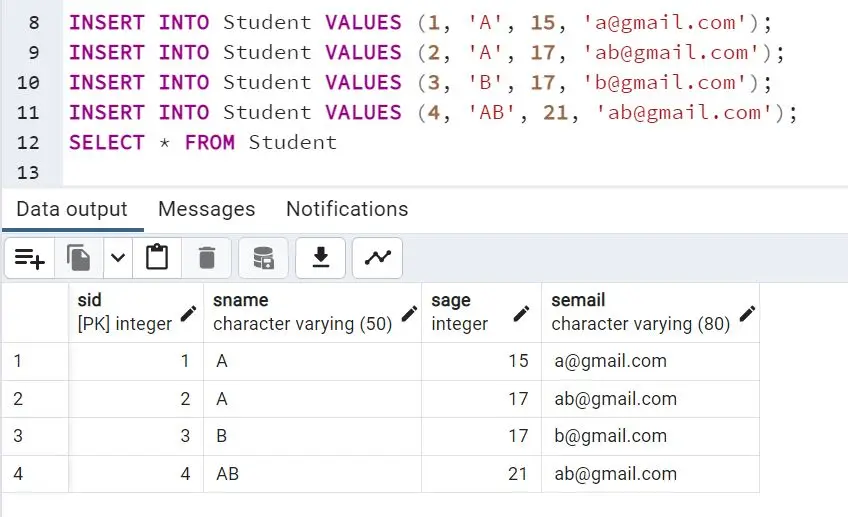
The schema is CREATE TABLE Student (sid INT PRIMARY KEY, sname VARCHAR(50), sage INT, semail VARCHAR(80));. The sample rows are (1, 'A', 15, 'a@gmail.com'), (2, 'A', 17, 'ab@gmail.com'), (3, 'B', 17, 'b@gmail.com'), and (4, 'AB', 21, 'ab@gmail.com'), inserted into Student (sid, sname, sage, semail).
Here sid is unique because it is the primary key. The other columns can repeat: the sample has two sname values of A, two sage values of 17, and two semail values of ab@gmail.com. The table-state image shows the supplied sample data.
Choose What Counts as a Duplicate
Decide the business rule before querying. To find repeated names, compare sname; to find repeated email addresses, compare semail; to identify repeated name-and-age pairs, compare both sname and sage. A row is a duplicate only with respect to the chosen columns. For example, the two A rows have different ages and emails, so they are duplicate names but not identical student details.
Treat nulls and text normalization according to the same rule. GROUP BY places null values in one group, so decide whether missing values should count as matches. If case or surrounding spaces should be ignored, use the same normalization expression consistently in both detection and deletion, such as lower(trim(semail)) for email comparison.
Find Duplicate Values and Rows
Run this small example to see how grouping by the chosen name column identifies repeated names. It illustrates the grouping rule with the sample rows; it does not execute PostgreSQL SQL.
from collections import Counter

students = [
    (1, "A", 15, "a@gmail.com"),
    (2, "A", 17, "ab@gmail.com"),
    (3, "B", 17, "b@gmail.com"),
    (4, "AB", 21, "ab@gmail.com"),
]
name_counts = Counter(student[1] for student in students)
for name, count in name_counts.items():
    if count > 1:
        print(f"{name}: {count}")
A: 2
For the PostgreSQL query, count duplicate names with SELECT sname, count(*) AS occurrences FROM Student GROUP BY sname HAVING count(*) > 1;. Add each comparison column to both the SELECT list and GROUP BY clause to detect duplicate combinations. For example, GROUP BY sname, sage finds repeated name-and-age pairs. HAVING filters groups after the rows have been grouped.
To list every row whose name belongs to a duplicate group, use SELECT * FROM Student s WHERE (SELECT count(*) FROM Student m WHERE m.sname IS NOT DISTINCT FROM s.sname) > 1;. IS NOT DISTINCT FROM treats two null names as a match, so this correlated count includes every row in a repeated null-name group as well as repeated non-null names. It repeats the comparison for each row and returns all matching rows, not just one summary per group. For large tables, the grouped query joined back to Student can be another way to inspect the matching rows.
For row-level selection, use ROW_NUMBER() OVER (PARTITION BY sname ORDER BY sid) and filter in an outer query with rn > 1. PARTITION BY defines duplicate groups; the ordering defines which row gets number one. A full-row comparison that includes sid cannot find identical rows in this schema because the primary key prevents two rows from sharing the same sid. To compare all descriptive values instead, group by sname, sage, semail; that detects matching details while ignoring the identifier.
Delete Duplicate Rows Safely in PostgreSQL
First inspect the exact rows that would be removed. The following pattern keeps the smallest sid in each repeated-name group and selects the rest: WITH ranked AS (SELECT sid, ROW_NUMBER() OVER (PARTITION BY sname ORDER BY sid) AS rn FROM Student) SELECT s.* FROM Student s JOIN ranked r USING (sid) WHERE r.rn > 1;. Use your chosen duplicate columns in PARTITION BY; change ORDER BY sid only if you have a documented survivor rule. An identifier order is deterministic, but it does not prove which row is newest.
After reviewing the preview, the corresponding deletion is WITH ranked AS (SELECT sid, ROW_NUMBER() OVER (PARTITION BY sname ORDER BY sid) AS rn FROM Student) DELETE FROM Student s USING ranked r WHERE s.sid = r.sid AND r.rn > 1;. The sid join targets only the rows selected by the ranking. Run the preview and deletion in a transaction when practical, and verify the affected rows before committing; take a backup or use your normal recovery process for important data. Do not use a name-only self-join with an inequality on sid: that can delete rows with the same name but differing other values, and its ordering alone does not establish recency.
Verify the Result and Prevent Recurrence
Repeat the grouped duplicate check using the intended comparison columns. For names, SELECT sname, count(*) FROM Student GROUP BY sname HAVING count(*) > 1; should return no duplicate-name groups if that was the cleanup rule. Also inspect rows that remain and confirm the selected survivor rule preserved the data you need.
To prevent future duplicates, add a UNIQUE constraint or unique index on the columns that represent the actual rule, for example UNIQUE (semail) if each non-null email must be unique. Check and resolve existing conflicts first. PostgreSQL unique constraints ordinarily allow multiple null values; if missing emails must also be unique, choose an explicit policy and enforce it accordingly. A constraint on sname would be inappropriate if different students may share a name.
Conclusion
Choose the comparison columns first, use GROUP BY or ROW_NUMBER() to inspect the resulting groups, and base deletion on a stable unique key. Preview and verify the selected rows before committing a destructive change. These steps make the meaning of “duplicate” explicit and help protect valid records.