HOWTO · Python
Derivative of ReLU Function in Python
The ReLU function is most frequently used in machine learning in terms of deep learning. This article discusses how to implement ReLU derivation in Python along with implementing the ReLU function.
On this page
ReLU is defined by f(x) = max(0, x). In Python, implement it with max for a scalar or numpy.maximum for an array. Its mathematical derivative is 0 for x < 0 and 1 for x > 0; at x = 0, the derivative is undefined. Code commonly chooses 0 there as a subgradient, and the examples below use that convention.
Implement the ReLU Function in Python
For a scalar input, the built-in max function directly expresses the definition. Run this example:
def relu(x):
    return max(0, x)


print(relu(3))
print(relu(0.5))
3
0.5
The function returns the input when it is positive and 0 otherwise. This scalar implementation expects one number at a time and does not apply directly to a NumPy array.
Implement the Scalar ReLU Derivative
For nonzero inputs, the derivative follows the slope of the piecewise-linear function: it is 0 below zero and 1 above zero. The mathematical derivative does not exist at zero because the left and right slopes differ. A program still needs a value there when computing gradients, so this function explicitly selects the common subgradient value 0:
def relu_derivative(x):
    return 1 if x > 0 else 0


for value in (-2, 0, 3):
    print(value, relu_derivative(value))
-2 0
0 0
3 1
The rule returns 1 only for strictly positive inputs, and returns 0 for zero and negative inputs. This is an implementation convention at the nondifferentiable point, not a claim that the mathematical derivative there equals 0.
Apply ReLU and Its Derivative to NumPy Arrays
NumPy applies these operations element by element. np.maximum computes ReLU, while np.where selects the derivative value for each array element. The derivative expression uses the same zero subgradient as the scalar function:
import numpy as np

values = np.array([-2.0, 0.0, 3.0])
outputs = np.maximum(values, 0)
gradients = np.where(values > 0, 1, 0)

print(outputs)
print(gradients)
[0. 0. 3.]
[0 0 1]
For array inputs, both printed arrays align element by element with values; entries at zero receive derivative value 0 under the chosen convention. Use np.maximum and np.where when the inputs are arrays, and the scalar functions above when each call handles one number.
Use Lambda Expressions for Scalar Inputs
A lambda expression is a concise option when a short scalar function is useful inline. These expressions use the same definitions and zero convention as the named functions:
relu = lambda x: max(0, x)
relu_derivative = lambda x: 1 if x > 0 else 0

print(relu(3), relu_derivative(3))
3 1
These lambdas accept scalar inputs; they are not a replacement for NumPy’s element-wise operations on arrays. For reusable logic or more explanation, named def functions are generally easier to read and extend.
Plot and Verify ReLU and Its Derivative
A plot makes the flat region and the slope change visible. The supplied plot uses 0 at zero for the derivative curve, matching the implementation convention; the mathematical derivative itself remains undefined at that point. The following self-contained check verifies representative values without requiring a plotting library:
points = (-2, 0, 2)
for x in points:
    relu = max(0, x)
    derivative = 1 if x > 0 else 0
    print(x, relu, derivative)
-2 0 0
0 0 0
2 2 1
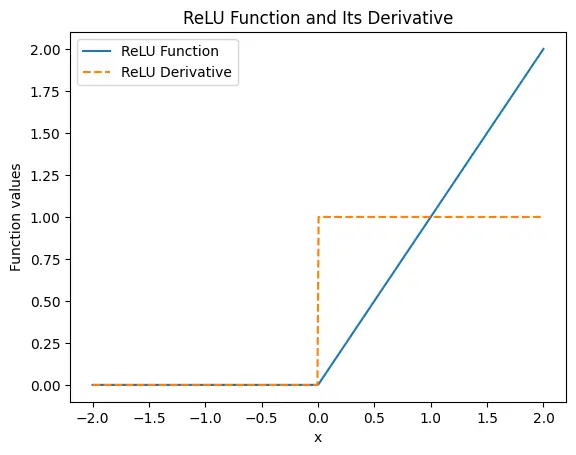
The ReLU curve stays at zero for negative inputs and rises with slope 1 for positive inputs. Its mathematical derivative is undefined at x = 0; the implementation above chooses subgradient 0 there. The dashed vertical connector marks the jump from 0 to 1 and does not represent intermediate derivative values. In neural networks, repeated zero gradients can stop some units from updating for negative inputs. Leaky ReLU is one alternative: it uses a small nonzero slope on that side.